Overview
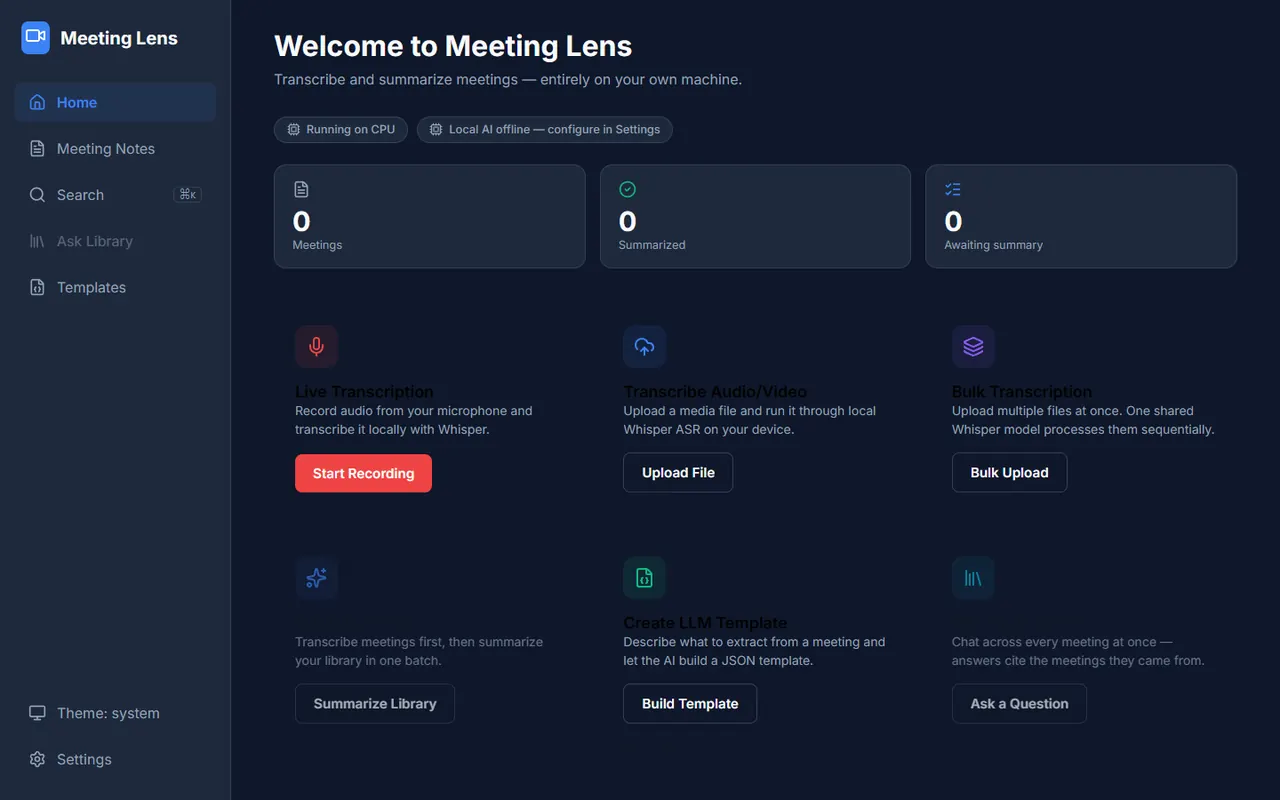
A meeting-intelligence tool built on two retrieval-augmented generation pipelines, one library-wide and one per meeting, so an answer can be traced back to the meeting and moment it came from. Five LLM providers sit behind a single abstraction, and transcription jobs survive a crash.
Highlights
- Two RAG pipelines, library-wide and per-meeting, over a sqlite-vec vector store for cited cross-meeting question answering
- Five interchangeable LLM providers behind one abstraction
- Crash-safe concurrent job processing with atomic file locking and orphaned-job recovery
Built with
- Python
- FastAPI
- sqlite-vec
- faster-whisper
- React
- TypeScript